Assembling complex 3D objects from multimodal inputs remains a significant challenge in computer vision. We introduce E-M3RF, an Equivariant Multimodal 3D Re-assembly Framework that leverages geometric equivariance to robustly align and assemble fragmented 3D parts guided by textual and visual prompts.
By inherently understanding the SE(3) equivariant properties of spatial components, our framework drastically reduces the search space for assembly configurations. E-M3RF establishes a new state-of-the-art on multiple 3D re-assembly benchmarks, proving highly resilient to noise and partial observations.
Method
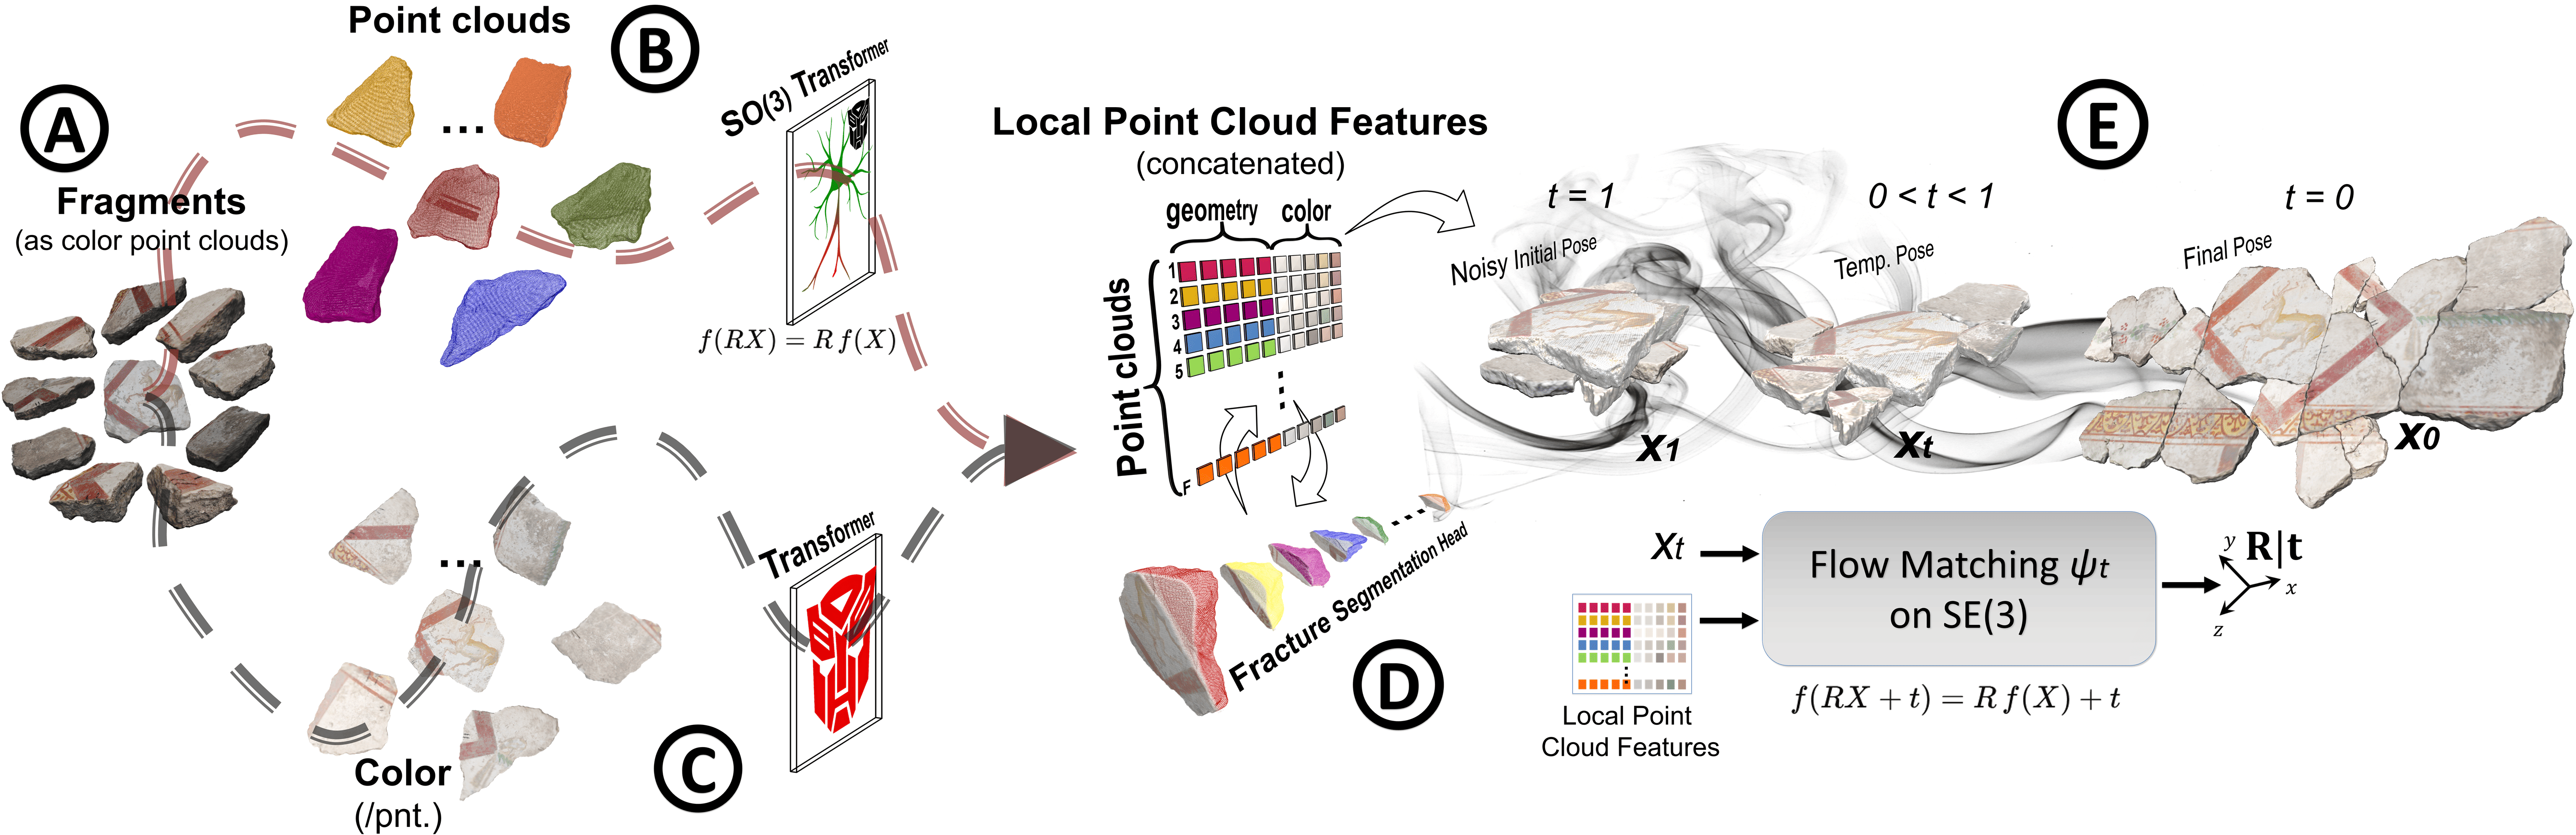
E-M3RF's pipeline.A A set of textured fragments (left) loaded as colored point clouds (w/ per-point RGB).
Two transformer encoders extract Bfracture-aware geometric features, which are geometrically equivariant, since they are processed by an SO(3)-equivariant Transformer so representations transform consistently under motions (rotation/translation) and Ccolor features through a Transformer over per-point colors which extracts dense color descriptors.
The streams are concatenated into Dlocal point-cloud features (xyz/rgb/normals tokens); the geometry stream is guided by a fracture-segmentation head during pretraining.
Using these fused features, we perform Eflow matching on SE(3): a time-dependent vector field ψt transports fragment poses from a noisy initialization x1 through intermediate states to the assembled configuration x0, yielding per-fragment transforms (R,t).
Results
E-M3RF vastly outperforms existing baselines across multiple challenging metrics. Below are the qualitative 3D re-assembly results across our evaluated synthetic and real-world cultural heritage datasets. Click on any animation to enlarge.
×
BibTeX
If you find our work helpful, please consider citing it:
@inproceedings{islam2026em3rf,
title = {E-M3RF: An Equivariant Multimodal 3D Re-assembly Framework},
author = {Islam, Adeela and Fiorini, Stefano and Lecha, Manuel and Tsesmelis, Theodore and James, Stuart and Morerio, Pietro and Del Bue, Alessio},
booktitle = {Proceedings of the European Conference on Computer Vision (ECCV)},
year = {2026}
}